Fleetgenius supports smarter fleet operations by bringing planning, tracking, and performance insights into a single workflow. This guide explains what Fleetgenius is in an objective, background-focused way—covering why fleets adopt centralized tools, how suppliers typically structure pricing, and what evaluation criteria teams should use to compare options responsibly.
Fleetgenius is commonly discussed in fleet-management contexts because it aims to help organizations coordinate day-to-day operations with clearer visibility into vehicles, routes, and performance signals. For fleet managers, logistics planners, and operations leaders, the key question is rarely “can we monitor vehicles?”—it’s “can we translate operational data into better planning, fewer avoidable disruptions, and more consistent service levels?” Tools in this category often sound similar at first glance, so the real differentiator becomes how well a platform fits your operational workflow, integrates with the systems you already rely on, and supports repeatable decision-making under time pressure.
This article addresses that decision process in a professional, objective way. It treats fleet platforms—whether Fleetgenius specifically or comparable systems—as operational instruments. Like any instrument, their value depends on what you measure, how you interpret it, and whether the organization has the discipline and governance to act on it. In many organizations, the most time-consuming problem isn’t the software itself; it’s clarifying responsibilities, standardizing definitions, and designing a workflow that turns raw signals (telematics events, maintenance logs, job completion statuses) into decisions (dispatch changes, route adjustments, maintenance prioritization, compliance documentation).
Very few fleet programs are “steady state.” Even mature operations teams experience constant variability: unexpected congestion, weather effects, partial vehicle breakdowns, driver availability changes, appointment window shifts, customer rescheduling, and emergent work orders that disrupt the day’s plan. As a result, fleet decisions tend to fall into repeating categories:
1) Short-cycle operational decisions (minutes to hours): When a delay occurs, operations teams decide whether to reassign jobs, adjust routes, accelerate dispatch priority, or communicate proactively to customers. These decisions require speed, context, and reliable job status tracking.
2) Medium-cycle decisions (days to weeks): Maintenance scheduling, utilization planning, readiness forecasting, staffing adjustments, and compliance checks usually fall within multi-day horizons. Here, historical data and predictive or rule-based insights matter.
3) Long-cycle decisions (months to quarters): Fleet modernization planning, vehicle replacement strategies, vendor negotiations, and policy development are longer-term initiatives. Platforms that improve data consistency and reporting quality make these decisions less guesswork-based.
Very fleet programs face recurring operational pressure points: rising fuel and maintenance costs, driver availability and scheduling constraints, service-level commitments to customers, and the need to respond quickly to delays. Tools marketed for fleet use—often including Fleetgenius—are designed to support workflows such as dispatch planning, route management, operational reporting, and asset oversight. The practical value typically depends on how well a tool integrates with existing systems (for example, telematics hardware, internal maintenance records, or enterprise resource planning tools) and how reliably data is captured and acted upon.
In other words, a fleet platform should not only “show information.” It should help an organization execute a workflow that can be repeated reliably—especially when something breaks, changes, or deviates. Many organizations discover that monitoring without operational closure (turning visibility into action) does not produce sustainable improvement.
From an industry perspective, centralized fleet intelligence reduces the “information gap” between what drivers experience on the road and what operations teams learn later. When data flows are inconsistent, teams often compensate with manual spreadsheets, duplicated reporting, or delayed reconciliation of work orders. For example, a driver might complete a job, but the operations team might not learn it until an end-of-day check. Or a maintenance technician might record work, but the dispatch team might not receive that update quickly enough to influence tomorrow’s plan.
In contrast, platforms positioned for fleet use—where Fleetgenius may fall depending on the organization—generally aim to reduce these gaps by aligning operational events with actionable reporting. That alignment has several practical effects:
Centralization also helps leadership trust the numbers. When teams use a single platform with standardized definitions, reporting becomes more consistent. Without standardization, it’s common for teams to argue about what a KPI means (“on-time” for one team might be “scheduled arrival,” while another team might interpret it as “completed job time”). The platform can only partially solve this—but it often becomes the catalyst for aligning operational definitions.
Because pricing and supplier structures vary widely by region, fleet size, and feature requirements, the very defensible evaluation approach is criteria-based. You’ll typically want to assess the fit across multiple dimensions rather than treating the decision as a single feature checklist.
Practical evaluation criteria often include:
(1) Data sources and quality: telementry signals, driver actions, odometer readings, incident reporting, and maintenance timestamps. If your data source is incomplete, the platform’s dashboards can be “accurate” yet still not useful.
(2) Workflow coverage: dispatch, routing, compliance checks, maintenance planning, and exception handling. A system that supports reporting but not operational workflows may improve visibility yet still leave dispatch decisions to manual processes.
(3) Reporting depth: operational KPIs tied to business objectives—utilization, uptime/downtime, job completion quality, and service-level performance. Reporting depth also includes whether KPIs are configurable and whether export options exist for deeper analysis.
(4) Usability: training burden for dispatch teams and managers. Usability includes the clarity of user interfaces and the practicality of daily workflows. If dispatchers must work around the system, adoption will drop.
(5) Implementation effort: integration and data migration. Even when software features are strong, time and cost often concentrate in onboarding: connecting telematics, mapping maintenance categories, migrating historic assets, and defining data ownership.
(6) Vendor responsiveness: support quality and escalation pathways. In a fleet environment, where operations demand continuity, support matters as much as features. A tool may look strong during a demo but underperform if issues take weeks to resolve.
A helpful approach is to evaluate “fit” as a chain: inputs feed workflows, workflows produce outputs, outputs support decisions, and decisions lead to measurable outcomes. Fleetgenius can only impact the last link in the chain if each previous link is implemented correctly.
When organizations compare Fleetgenius with alternative fleet solutions, pricing is usually influenced by a mix of licensing approach (per vehicle, per user, or tiered plans), expected integrations, and ongoing support. Rather than assuming a single “top price,” procurement teams often ask suppliers to provide a tailored quote that clarifies:
However, “responsible” price evaluation is not only about cost. It also involves understanding total cost of ownership (TCO), including:
Cost comparisons also must consider the fact that two systems with similar license pricing can have materially different requirements. For example, one supplier might include a connector for your maintenance system out of the box, while another might require custom mapping or API work. Another system might charge for the right to configure KPIs, while another includes it. The reliable approach is to request a line-item quote and then map each line item to your evaluation criteria.
If you have a specific “price” quote or supplier proposal in hand, the very reliable next step is to map those line items to the evaluation criteria above—ensuring you’re comparing “apples to apples,” not just headline cost.
Across logistics and field services, fleet modernization has been driven by the need to improve operational planning accuracy and reduce avoidable downtime. While specific performance outcomes vary by industry segment and implementation quality, credible industry analyses commonly emphasize process visibility, asset utilization, and data-driven maintenance planning as recurring themes. For broader context on fleet and telematics trends, organizations often reference material from established industry bodies and market research providers, such as the Global Telematics Market reporting streams (commonly covered by firms like Allied Market Research and other research houses) and guidance from regulators and standards organizations where compliance is relevant.
Source note: For market sizing or adoption rates, consult the latest published reports from recognized market research firms and official industry/regulatory publications, because figures change year to year and differ by region and fleet segment. This article avoids citing specific numeric claims that cannot be verified directly from the user’s provided inputs.
What matters for your decision is less the exact adoption percentage and more the direction of change: organizations that unify operational signals and enforce workflow discipline tend to achieve better operational consistency. That direction is supported by the evolution of telematics hardware (more sensor coverage, more stable data capture), connectivity improvements (more reliable data transmission), and increased maturity of fleet software stacks (workflow-centric rather than purely dashboard-centric).
In practical terms, adopting a fleet platform is often justified by a few repeatable problem patterns:
Fleetgenius-style systems are frequently selected to address these patterns, but the implementation must be designed to close the operational loop.
In operational practice, fleet tools help teams manage variability: traffic, delivery windows, work order prioritization, vehicle availability, and driver hours. A platform such as Fleetgenius may support dispatch planning through centralized assignment workflows, route visualization, and operational updates that reduce back-and-forth communication. The strategic aim is to shorten the cycle between “a change occurs” and “a response is executed.”
Dispatch and routing support usually includes several core capabilities. While exact feature sets vary, the typical workflow looks like this:
Where Fleetgenius adds value depends on how well it supports the steps above, especially steps 4 and 5. Many organizations have accurate job intake and assignment in place, but they struggle with execution monitoring and exception handling. When those are improved, dispatch decisions become more consistent.
Route visualization matters because it supports situational awareness. For example:
However, the reliability of routing support depends on data inputs. If telematics signals are delayed or if job completion statuses are not recorded accurately, route visualizations can mislead. Therefore, evaluation should test workflows using your real data or realistic case scenarios.
Many fleets pursue platforms to improve maintenance planning and utilization. Common use cases include:
However, an expert perspective is to treat “ROI” as dependent on data quality and process adoption. A well-designed system can improve visibility, but teams still must standardize how they request, approve, and record maintenance and dispatch decisions. Without operational discipline, maintenance planning remains fragmented: dispatchers might not reflect updated availability quickly; technicians might record work in formats that don’t map to the system; or work order closure might be delayed, which then undermines utilization statistics.
To make maintenance and utilization improvements measurable, consider evaluating the system’s ability to support the following:
When these elements exist and are implemented correctly, utilization becomes more than a “vehicle is on/off the road” metric. Instead, it becomes a driver for operational decisions. For example, if an asset class has recurring downtime due to a specific failure mode, you can adjust maintenance practices or procurement strategies.
One reason fleet platforms succeed or fail is the practical implementation path. Even the very capable tool can underperform if:
When Fleetgenius (or a comparable solution) is introduced, many organizations benefit from a phased rollout. A phased rollout can reduce operational disruption and allow teams to prove data accuracy before scaling. A typical approach could be:
This phased design helps because it reduces the “unknowns.” In early implementation, the biggest risk is usually not whether the platform exists; it’s whether your data flows and operational definitions will hold under real daily pressure.
Training is particularly important because dispatch and maintenance involve different roles with different daily tasks. If training is only manager-facing, dispatchers may still struggle to use the system correctly. If training is only dispatch-focused, managers may not understand how to interpret KPIs, which undermines leadership support and continued usage.
Data discipline includes decisions like:
Platforms help, but the organization still has to adopt the discipline. Without that, the platform becomes another system that people avoid or use inconsistently.
The following supplement is intended to help you evaluate Fleetgenius against alternatives using a structured approach. It rephrases the broader “additional important information” concept into a comparison table, a step-by-step guide, and explicit requirements. This structure is useful because it turns vendor discussions into verifiable evidence. When a vendor cannot provide artifacts or sample outputs, it often indicates a gap between marketing claims and the reality of implementation.
| Dimension | What to compare for Fleetgenius-style platforms | Conditions/requirements to verify | Practical “source” you can request from the supplier |
|---|---|---|---|
| Pricing structure | Tier definitions, per-vehicle/per-user model, integration fees, support plan options | Written quote that separates license, onboarding, and integration scope | Formal pricing sheet and a scope-of-work document |
| Data sources | Which telematics providers or hardware models are supported | Documented data fields and sample payloads; clarity on latency expectations | Integration documentation and data dictionary |
| Core workflows | Dispatch, routing visualization, job status updates, exception handling | Evidence that your required workflows exist end-to-end (not just “reports”) | Workflow demo script or sandbox environment credentials |
| Reporting and KPIs | Coverage of uptime/downtime, on-time delivery signals, maintenance history views | Confirm whether KPIs are configurable; validate export formats | Sample dashboards, report templates, and export tests |
| Security and governance | Role-based access, audit logs, encryption and retention policy | Written security posture and data handling terms | Security overview and data-processing documentation |
| Implementation support | Training plan, onboarding timeline, and change-management approach | Defined responsibilities between your team and the supplier | Implementation plan with milestones and acceptance criteria |
Fleetgenius is typically discussed as a fleet-management support tool—often connected to dispatch coordination, operational visibility, and performance reporting. Exact features depend on the supplier’s plan, integrations, and deployment scope. The safest approach is to validate capabilities during a scoped demo and request written scope details, particularly how dispatch exceptions and job closure are handled.
Pricing models for fleet platforms often vary by plan tier and may depend on fleet size, number of users, and integration requirements. Instead of relying on assumptions, request a line-item quote that separates licensing, onboarding, integration, training, and support terms so you can compare total cost of ownership fairly. Also ask whether configuration work (such as KPI setup or workflow adjustments) is included or billed separately.
Ask for a scope-of-work document, integration documentation, a data dictionary (fields and definitions), onboarding and training plans, security posture and data-processing terms, and support escalation procedures. These items help you confirm readiness beyond marketing claims. Additionally, request sample exports and sample dashboards that reflect your KPIs, not only generic demo visuals.
Integration is the core variable. Fleet platforms generally integrate with certain telematics providers or systems, but compatibility depends on supported hardware, available APIs, and the format of your existing maintenance records. Request a compatibility checklist and—where possible—test a data flow in a sandbox. If the maintenance system is custom, confirm how mapping and transformation are handled.
Common risks include incomplete data capture, inconsistent operational definitions, undertrained dispatch teams, and scope creep during implementation. Mitigate these by defining acceptance criteria, validating data fields early, rolling out in phases, and documenting responsibilities between your team and the supplier. Also risk-assess connectivity or telematics outage scenarios so operations can continue smoothly.
Choose KPIs tied to your operational goals, such as on-time job completion, reduced time-to-dispatch updates, fewer unresolved maintenance exceptions, improved vehicle availability planning, and reduced administrative rework. Ensure KPIs use consistent definitions and confirm how the platform calculates them. To make measurement credible, plan a baseline period before rollout.
Often, the workflow value still applies, but implementation effort and integration complexity become more visible at smaller scales. Small fleets may prioritize speed of onboarding and minimal change to daily routines, while larger fleets may prioritize deep reporting and governance. For smaller fleets, you still need data discipline—just lean on fewer workflows first and scale later.
Yes. If you operate near specific regulatory frameworks related to vehicle operation, safety reporting, or driving time rules, confirm audit trail capabilities and reporting formats. Local procurement practices and language support may also affect implementation timelines. You should also review data residency and retention requirements, especially if operations span multiple regions.
Even when you follow a structured evaluation process, there are subtle factors that often determine real-world outcomes. These factors can be particularly important in organizations where teams have established processes that cannot change overnight.
1) Workflow realism under exception pressure: Many demos show smooth success cases (jobs completed on time, vehicles available, maintenance scheduled). But real value is often revealed under exceptions: what happens when a job is late, when a vehicle is unexpectedly offline, when a driver swaps routes, or when a maintenance issue delays completion. Ask to see the system’s exception workflow end to end: how exceptions are recorded, who gets notified, what actions are suggested or required, and how closure is tracked.
2) Role-based views and operational ergonomics: Dispatchers, managers, technicians, and compliance officers all need different views. If the system’s UI is difficult for dispatchers but detailed for managers, adoption can fail. Request role-based screenshots or pilot access so you can assess whether common daily tasks are performed efficiently.
3) Definition governance and KPI comparability: KPI comparisons over time matter. If “on-time delivery” can be reconfigured, then KPI trends might shift after changes in definitions. Confirm how configuration changes are logged and whether historical KPI calculations remain consistent or are recalculated. If recalculation occurs, ensure you can explain changes to internal leadership.
4) Data reconciliation and dispute resolution: In operations, disagreements happen. A driver may indicate a job was completed, while the system records it differently. A technician might record work hours but maintenance closure might not be reflected for dispatch planning. Ask how the system supports reconciliation: is there a workflow for correction, and does it maintain audit trails?
5) Exportability and integration to your analytics stack: Many organizations eventually want to use fleet data in dashboards outside the platform. Confirm whether exports are flexible (CSV, API access, scheduled reports), whether exports can include key fields you need, and whether there are limits. An otherwise good fleet platform can become a bottleneck if data export options are restrictive.
6) Offline or low-connectivity resilience: In some fleets—rural routes, low-signal areas, remote worksites—connectivity can be unreliable. Ask how the platform handles delayed telematics uploads, buffering, and timestamp corrections. Also clarify whether exceptions are queued and later reconciled.
Security and governance are often treated as procurement checkboxes, but they also support day-to-day operational confidence. When an organization trusts data, teams use it more consistently. When governance is unclear, teams revert to manual processes “just in case.”
Governance and security considerations often include:
For compliance-driven fleets, auditability is essential. Many fleets must demonstrate that maintenance was performed, that vehicles were inspected, or that operational policies were followed. A fleet platform that supports audit trails reduces the manual work required to assemble evidence during audits.
When fleets go live with a new platform, the operational environment becomes more sensitive to disruptions. If an integration fails on day two, dispatch teams need rapid resolution. If there is confusion about how to close a maintenance work order, managers need clear guidance quickly. Therefore, vendor responsiveness can directly impact the success of Fleetgenius adoption.
When assessing support and implementation, evaluate:
Also evaluate the vendor’s ability to help during data quality issues. In practice, data quality problems often appear first as “missing fields,” “unexpected null values,” or “inconsistent status transitions.” Strong support teams treat these as solvable technical problems with clear fixes, rather than dismissing them as “user errors.”
Most fleet leaders want KPIs, but not all KPIs are equally actionable. Some KPIs become vanity metrics that don’t help dispatchers or maintenance teams make better decisions. To avoid this, KPIs should be designed with the operational workflow in mind.
For example, a KPI such as “average lateness” may be less actionable than “time-to-confirm vehicle availability” or “time-to-communicate exception status to customers.” Similarly, “utilization rate” may be misleading if it doesn’t account for planned versus unplanned downtime. A platform like Fleetgenius can help provide raw data, but you still need KPI design and governance.
Consider a KPI framework that includes:
Also ensure KPIs use consistent definitions across your organization. If different teams interpret “completed” differently, you may see conflicting KPI trends. Fleet platforms can enforce consistent status transitions if configured properly, but governance is still required.
Adoption is where many fleet platform projects fail quietly. The platform may be technically accurate but operationally underused. This can happen if the system is introduced without process redesign, or if teams are allowed to keep old manual steps “on the side” indefinitely.
To support adoption, consider:
When adoption succeeds, the platform becomes the “system of record” for job status and maintenance decisions. That shift is what makes centralized fleet intelligence truly valuable.
Even well-scoped rollouts require planning. The timeline is influenced by integration complexity, data readiness, and training needs. A realistic timeline typically includes:
Ask suppliers for a timeline that includes acceptance criteria at each step. A supplier that provides only a “go-live date” without specifying what must be true by that date can create implementation risk.
It can be helpful to frame expectations clearly. A fleet platform like Fleetgenius can improve how operational data is captured, structured, and used, but it cannot replace the fundamental needs of operational decision-making. Specifically:
What a good fleet platform can do is reduce latency, standardize workflows, improve traceability, and provide actionable visibility. When those improvements are paired with disciplined operations and governance, fleets often see measurable improvements.
In fleet operations, the very meaningful improvements usually come from aligning tool capabilities with real workflows—dispatchers need usable processes, maintenance teams need consistent recordkeeping, and managers need KPIs they can trust. Fleetgenius may serve as one of the platforms organizations consider when building that alignment. If you approach the evaluation with clear success criteria, a scoped supplier quote, verified integration paths, and a disciplined rollout plan, you’ll be in a stronger position to make a decision grounded in operational fit rather than promotional messaging.
To make the decision process even more concrete, remember that the best evaluation is not a comparison of feature names. It’s a comparison of operational outcomes under realistic conditions: Can the system support your dispatch decisions when exceptions occur? Can it standardize job closure and maintenance availability status in a way that dispatchers and managers trust? Can your team adopt it without excessive manual work? Those are the questions that determine whether a Fleetgenius-style platform becomes a practical foundation for fleet decisions—and not just another software tool in the ecosystem.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans

Explore the Tranquil Bliss of Idyllic Rural Retreats

How to Make Lasting Memories at Disneyland Attractions

4rkojvsx Technology: Industry Insights and Buying Guide

Affordable Phones and Plans for Seniors

Affordable Full Mouth Dental Implants Near You

Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!

Discovering Springdale Estates

Unveiling RS Sul Telecom Services

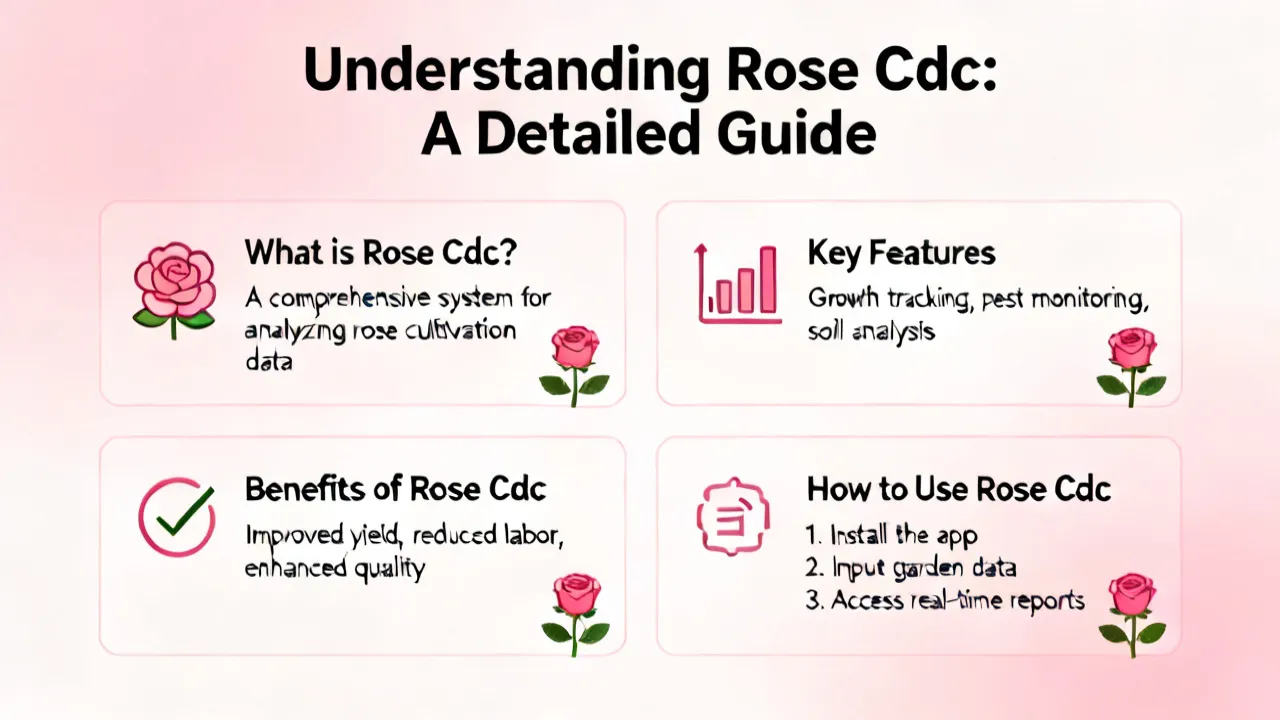
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.
