This guide explains how Fleetgenius supports day-to-day fleet decision-making with a practical, expert approach to configuration, supplier evaluation, and operational readiness. Objectively, fleet management tools typically consolidate routing, compliance tracking, maintenance planning, and performance reporting to help organizations coordinate vehicles, drivers, and service providers with consistent governance.
Fleetgenius is commonly positioned as a fleet-operations platform that helps organizations standardize how vehicles are planned, monitored, and maintained. For fleet leaders, the practical goal is not only “visibility,” but operational discipline: clearer responsibilities, repeatable workflows, and audit-ready documentation for day-to-day movement, maintenance cycles, and supplier interactions. The sections below provide an objective industry-informed framework for evaluating fleet workflows and aligning stakeholders around predictable outcomes. While every organization’s context differs—fleet size, regulatory environment, vehicle class, internal governance model—the core readiness questions tend to rhyme across industries. The better you can define the operational “how” (process) and the operational “why” (measurable outcomes), the better chance you have that Fleetgenius (or any comparable platform) becomes an operational control layer rather than another disconnected system.
Very fleet environments—ranging from municipal services to private logistics—share the same operational pressure points: vehicles must be available when needed, downtime must be minimized, compliance requirements must be met, and costs must be forecastable. Fleet management platforms address these areas by consolidating data sources and supporting standardized processes rather than relying solely on individual spreadsheets or ad-hoc communication.
In many organizations, the daily reality looks like this: a dispatcher tries to build a schedule, maintenance receives an urgent request, compliance asks for proof of an inspection, and finance wants to reconcile costs to work performed. Each function may be “doing its job,” but the information handoffs can be inconsistent. A modern fleet platform matters because it compresses time between an operational question and a reliable operational answer. Fleet leaders typically define the “time-to-answer” problem as a business constraint. When it takes hours (or even days) to confirm which assets are serviceable, which inspections are overdue, or which work orders are pending supplier confirmation, operations drift into reactive mode.
From an industry perspective, fleet tools tend to add value when they reduce the “time-to-answer.” For example, when a dispatcher asks, “Which vehicles are due for service this week?” or “Which drivers have pending documentation?” the system should return accurate, timely information without manual cross-checking. Fleetgenius, in this context, functions as the operational backbone that supports faster decisions and consistent execution.
It is also worth recognizing that “visibility” alone does not create readiness. A team can have dashboards and still struggle if workflows are not defined. Many operations face the opposite scenario: people can see what’s happening, but they cannot standardize what should happen next. That is why readiness evaluation should focus on workflow design, governance, and documentation discipline. Fleetgenius matters because it can become the system of record for asset state changes and work execution—assuming implementation is treated as operational change management, not just software configuration.
While every organization’s needs differ, fleet platforms generally fall into functional categories. Fleetgenius implementations are typically assessed based on how well they cover these categories end-to-end:
An expert lens focuses on implementation fit: the software may have many features, but the organization’s greatest gains come when the workflow design matches real-world operations. To evaluate fit, fleet leaders often ask: “What is the operational trigger, what is the required response, who approves it, what evidence is stored, and how does the system prevent inconsistent outcomes?” In other words, readiness is less about whether the system can store information and more about whether it can enforce decision rules and evidence capture.
Additionally, capability evaluation should consider operational maturity. If your organization is still building basic master data and struggling to close work orders consistently, then compliance and reporting features may not be the first lever. Conversely, if your organization already has disciplined maintenance cycles but suffers from fragmented visibility across dispatch and compliance, then integration and workflow synchronization become higher priority.
Fleet operations are also supplier operations. Maintenance, repairs, inspection services, and sometimes fuel or leasing relationships depend on reliable information flow. A platform like Fleetgenius can help if it supports structured intake of supplier work, clear service status transitions, and consistent evidence capture (e.g., service completion notes, invoice linkage, or inspection results where permitted by policy).
To avoid downstream friction, fleet leaders should evaluate:
In practice, supplier readiness is often the “hidden variable.” A system may support elegant workflows, but if suppliers respond with inconsistent formats, delays, or incomplete evidence, your internal processes can still degrade. Therefore, readiness evaluation should include a supplier workflow model: what information is required at request, what information is returned at completion, and what happens when suppliers miss deadlines or submit partial data.
Fleet leaders also need to consider contract-driven realities. Some suppliers may have contractual SLAs for turnaround time; others may be paid per job or per hour. A platform can help align supplier events to internal work order states, but governance matters: your system needs a consistent definition of what “completed” means. For example, is a work order “complete” when the supplier signals completion, when the invoice is approved, when parts are reconciled, or when inspection evidence is uploaded? If the platform’s configuration does not match your internal definition of closure, reporting becomes unreliable and teams start to “work around” the tool.
Finally, supplier coordination intersects with data ownership. Who owns asset condition updates? Is it the supplier, the maintenance planner, or a central fleet operator? The system should support role-based evidence capture so that internal ownership is clear while supplier information remains traceable.
When organizations compare fleet solutions, they often reference “price information” in procurement discussions. However, fleet software pricing is frequently customized based on factors such as the number of vehicles/assets, modules required, user seats, integration needs, and support level. Because published pricing can vary by contract and time, it is top practice to treat any quoted figure as conditional until confirmed in a written proposal or commercial agreement.
From a procurement governance standpoint, consider requesting:
This approach allows you to compare total cost of ownership rather than relying on a single headline number. It also reduces the risk of “functional misalignment,” where the purchase is priced for one set of modules but the organization later realizes it also needs integration work, data cleanup, training, or supplier workflow enablement.
Procurement should also ask for commercial clarity on how changes are handled. For example, if your fleet expands mid-year, what is the pricing model for additional assets or additional locations? If you discover you need a new compliance workflow due to a regulatory update, is that configuration included in baseline support or billed separately? Many organizations focus on the initial purchase and neglect change control terms, but operational readiness depends on the ability to evolve workflows safely and consistently.
Another readiness-related cost factor is implementation effort. If your organization has poor master data or inconsistent service history, implementation costs can increase due to data cleanup and validation. Procurement should therefore treat data readiness as a scope variable, not an assumption.
Experienced fleet managers often describe implementation as two parallel tracks: the technical setup and the operational adoption. Fleetgenius deployments are very successful when they include:
In other words, the “system” should not merely store information; it should guide people toward consistent decisions. This distinction is crucial. Many platforms can be technically configured quickly, but adoption requires behavioral change: people need to trust the workflow definitions, trust the master data, and trust the reporting logic.
Operational readiness also includes a “go-live contract” between functions. Dispatch, maintenance, compliance, and finance need to agree on what happens on day one and what changes afterward. If dispatch expects immediate asset status accuracy but maintenance is still learning the work order process, the organization may experience early friction. A readiness approach should therefore define phased rollout strategies, such as enabling maintenance workflows first, then enabling dispatch assignment controls, then enabling compliance evidence workflows.
Finally, operations running includes continuous improvement. Fleet workflows evolve due to supplier performance, regulatory changes, and shifting business priorities. A platform becomes operationally valuable when there is a governance rhythm: review overdue items, review exceptions, correct misconfigured states, and improve templates. Without this rhythm, the system can deteriorate into an untrusted repository.
Fleet organizations rarely operate in a vacuum. Even within the same country, rules and working practices can differ by municipality, industry, and service type. In “nearby” contexts—meaning operations serving a shared regional area—fleet leaders often need to align scheduling and documentation cycles with local realities such as inspection centers’ hours, common downtime windows, and vendor response patterns.
Local teams also tend to use familiar workplace language. For example, dispatchers may talk in terms of “vehicle readiness windows,” while maintenance planners focus on “service backlog” and “parts availability.” A good Fleetgenius rollout translates those internal terms into the system’s states and workflows so staff can adopt the platform without constant re-interpretation.
Localization is not limited to language. It includes operational cadence. For instance, certain fleets may run maintenance planning weekly, while others run it daily. Some compliance tasks require monthly evidence uploads; others follow quarterly cycles. Localization should ensure that reminders, due date logic, approval thresholds, and escalation pathways align to the organization’s actual cadence. Otherwise, teams experience alert fatigue or miss critical events.
There is also a cultural and managerial dimension. If local supervisors expect a certain escalation chain (e.g., notify a regional manager for any compliance exception above a threshold), the platform’s approvals and exception handling should reflect that chain. When approvals do not match local governance expectations, work may stall and the system becomes “bureaucratic,” reducing adoption.
In multi-site organizations, localization also intersects with data governance. Even if the system is centrally managed, you may need site-specific templates, site-specific supplier categories, and site-specific inspection evidence rules. Readiness planning should therefore include a question: what is centralized, what is localized, and how will consistency be enforced?
The following table provides a structured supplement to help you evaluate and operationalize a Fleetgenius-oriented approach. It compares common decision inputs, a practical step sequence, and typical conditions/requirements.
| Evaluation Component | What to Compare (Objective Criteria) | Step-by-Step Guide | Conditions / Requirements |
|---|---|---|---|
| Operational Scope | What fleet functions you need: planning, maintenance, compliance, reporting, and any integrations. |
1) Map your current workflows. 2) Identify gaps. 3) Prioritize must-have modules. 4) Document success metrics. |
Cross-functional sign-off (dispatch, maintenance, compliance, finance). |
| Data Readiness | Vehicle records, driver records, service history, and asset identifiers quality. |
1) Audit data fields. 2) Define required templates. 3) Run a test import. 4) Validate exceptions and corrections. |
Named owner for data quality; agreed master data rules. |
| Supplier Workflow Fit | How repairs and service tickets are created, tracked, and closed with suppliers. |
1) Define request and closure states. 2) Determine evidence requirements. 3) Pilot with one or two supplier categories. 4) Expand after review. |
Supplier participation depends on internal processes and contractual allowances. |
| Governance and Permissions | Role definitions and approval workflows for operational actions. |
1) List user roles. 2) Define permissions boundaries. 3) Create approval rules. 4) Validate with trial users. |
Access control policies aligned to internal security requirements. |
| Implementation and Support | Onboarding timeline, training coverage, and support escalation practices. |
1) Request implementation plan. 2) Plan training sessions. 3) Define go-live criteria. 4) Set a post-launch review schedule. |
Availability of key personnel during onboarding; defined escalation contacts. |
| Risk Management | Operational risk: downtime, compliance gaps, data errors, and reporting inaccuracies. |
1) Identify risks. 2) Create mitigation actions. 3) Establish rollback/contingency steps. 4) Monitor post-go-live indicators. |
Defined acceptance testing; documented contingency procedures. |
Sources note (methodological): For industry-wide top practices in fleet operations and asset management, organizations often rely on guidance from established bodies such as the American Trucking Associations (ATA), the International Organization for Standardization (ISO) asset management practices (e.g., ISO 55000 series), and compliance-focused regulatory documentation relevant to their operating jurisdiction. For telematics/connected vehicle considerations, industry analyses are commonly published by research firms such as Gartner and public-sector transport agencies; always verify applicability to your region and vehicle class.
When you treat the table as a readiness checklist, you can avoid common procurement pitfalls. The most frequent pitfall is to evaluate the platform as if it were a purely technical deployment. The second pitfall is to evaluate it as if it were a purely “maintenance” tool. In mature fleet operations, readiness depends on how maintenance, dispatch, compliance, and supplier workflows interact. A platform must coordinate state transitions across functions, not just within one department.
Below is a practical walkthrough designed to make Fleetgenius operational in a way that supports consistent decision-making. Treat this as a blueprint you can customize to your organization. The walkthrough should be paired with governance documents that define ownership, escalation, and success measures. Without these companion documents, implementation teams may configure workflows but fail to drive adoption.
Before configuration, define measurable outcomes. Examples include reduction in “unplanned downtime events,” faster maintenance scheduling response time, improved inspection documentation completeness, or improved asset availability forecasting accuracy.
To make outcomes measurable, avoid vague metrics like “improve visibility.” Instead, define baseline and target values. For example: unplanned downtime events per 100 vehicles per month; average cycle time from work order creation to completion confirmation; percentage of compliance tasks with complete evidence attached; average days overdue for inspections; percentage of assets with complete service history; and number of work orders closed without required fields.
Also consider operational risk outcomes. Fleet readiness is not only performance; it is risk management. If the platform reduces the chance of missing a critical inspection, the measurable outcome might be “reduction in late compliance events” or “reduction in compliance exceptions that require manual follow-up.” Those are often more valuable than broad dashboard aesthetics.
Document how work requests happen today. Then document exceptions: urgent breakdowns, parts delays, undocumented repairs, last-minute job changes, and how teams communicate across shifts.
Workflow mapping should include both the “happy path” and the “edge cases.” Many fleet failures occur in edge cases. For instance, a vehicle might be available but flagged due to missing documentation; the fleet still needs to operate. Or a supplier might complete work but delay uploading evidence. Your workflow design should anticipate these scenarios.
As part of workflow mapping, define triggers. For example: “inspection due date reaches today” triggers a compliance action; “work order created” triggers assignment to maintenance planner; “supplier marks complete” triggers internal evidence validation; “approval granted” triggers closure of work order. When triggers are clear, configuration becomes more predictable and reporting becomes more trustworthy.
Standardize naming for assets, locations, driver identities, service types, and supplier categories. Fleet platforms become more valuable when the system’s “vocabulary” matches how the organization already thinks, but with tighter definitions.
Master data readiness includes more than formatting. It includes establishing unique identifiers and preventing duplicates. For example, vehicle records should have a consistent asset ID used across dispatch and maintenance. If asset tags are inconsistent, “due for service” logic can fail and teams will lose trust. Similarly, supplier categories should be consistent so that reporting can group performance and costs correctly.
Master data standards should also define “source of truth.” For example, is the service history created in Fleetgenius or imported from an existing maintenance system? If both systems exist during transition, decide which fields are authoritative and which are overwritten.
Also plan for data lifecycle. Assets move between locations and may change assignments. Drivers may be replaced. Service intervals may be recalibrated. A readiness approach should define how changes are managed: who updates master data, when changes are allowed, and how updates are versioned or audited.
Set up permissions so that people can only perform actions appropriate to their roles. Define workflow states for maintenance requests and approvals, including what constitutes completion.
Roles and approvals are where operational governance becomes tangible. Fleet leaders should ensure that decision rights align with operational responsibilities. For example, who can mark an asset as “available” if compliance documentation is pending? If a maintenance planner marks a work order complete without evidence validation, compliance risk increases. Permissions should therefore reflect control points.
State configuration should align with how work progresses operationally. A common best practice is to keep state definitions mutually exclusive and clearly described. Avoid ambiguous states like “in progress” without explanation. Instead, create states like “scheduled,” “awaiting parts,” “awaiting supplier completion,” “evidence required,” “approved for closure,” and “closed.” This makes reporting precise and reduces operator interpretation.
Approvals should also reflect thresholds. Some fleets might require approval for any work order above a cost limit; others might require approval only for compliance exceptions. Your readiness evaluation should ensure the platform supports this threshold logic and that approvals are auditable.
Choose one operational area—such as scheduled maintenance for a subset of vehicles or a specific supplier workflow category. A bounded pilot reveals hidden requirements without disrupting the entire fleet.
Pilots should be designed to learn, not to “prove the software.” Therefore, identify what you want to learn. Examples include: whether dispatch workflows align with maintenance state changes; whether evidence requirements are captured correctly; whether supplier workflow states match real supplier behavior; whether reporting aligns with operational definitions; and whether training produces consistent outcomes.
During the pilot, collect feedback systematically. Don’t rely on informal comments only. Consider logging recurring issues by category: missing data fields, unclear instructions, states that don’t match operational reality, reporting misinterpretation, and user friction. Those insights help configure the final workflow before expansion.
Confirm that dashboards and reports reflect operational reality. For example, ensure service “due dates” align with your actual interval rules and that asset status transitions match operational definitions (e.g., “in service,” “available,” “inspection pending”).
Reporting validation should include logic tests. For instance, run test cases with known due dates and known service histories. Confirm that the platform flags due tasks at the right times. If interval rules are based on mileage, hours, or calendar days, ensure the computation matches your operational policy. Also validate that the reports count work orders correctly by state, not just by created or updated timestamps.
It is also important to validate cost reporting logic. If a work order includes parts and labor costs from multiple sources, confirm that the system attributes costs correctly to the work order and time period. Finance often cares about reconciliation and audit trails. A readiness approach should therefore include finance stakeholders in reporting validation.
Training works top when it mirrors what staff actually do. Use real examples: a vehicle flagged for inspection, a maintenance backlog scenario, or a supplier delay case requiring exception handling.
Scenario-based training should cover both routine and non-routine events. Routine events might include creating a work order from a scheduled maintenance interval. Non-routine events might include: a vehicle becomes unavailable due to an unplanned breakdown; a supplier returns partial evidence; an inspection is rescheduled; or a driver’s documentation is incomplete and the fleet must apply an exception policy.
Training should also address “data hygiene.” Users should learn not only where to click but how to ensure required fields are complete. A practical approach is to provide job aids: templates for creating a work order, a checklist for closing a work order, and an evidence checklist for compliance tasks. When training includes these checklists, adoption tends to improve.
Set criteria for go-live readiness (data completeness threshold, workflow acceptance tests, and approval chain confirmation). Avoid a go-live that only checks technical connectivity.
Readiness criteria should be measurable. Examples include: data completeness above a defined threshold for asset identifiers and service interval parameters; at least X% of imported records pass validation; workflow acceptance tests show that states transition correctly in pilot; approval workflows route correctly and are tested for each relevant role; evidence capture works for at least one compliance scenario; and reports match baseline operational definitions.
Go-live should also include operational contingency. What happens if a workflow fails due to a configuration error? What happens if an integration temporarily fails? What fallback system will dispatch use? The platform should have a “plan B” so that critical operations do not stall during early days.
After go-live, review process performance weekly. Track where users need guidance, where data quality degrades, and which workflow states cause confusion. Update SOPs and configurations accordingly.
Monitoring should focus on both adoption and accuracy. Adoption metrics might include: number of users actively creating and closing work orders; percentage of events completed in the system rather than externally; number of users requiring support; and turnaround time for approval queues. Accuracy metrics might include: compliance evidence completeness; frequency of missing required fields; discrepancies between reported and operational counts; and number of work orders closed without evidence or without approvals.
Document improvements. Each change in workflow or configuration should be captured with an explanation, the operational reason for the change, the users impacted, and the expected outcome. This documentation supports future audits and prevents “tribal knowledge” from replacing formal process.
From an operational excellence perspective, fleet platforms deliver the largest returns when they tackle three persistent problems:
Fleetgenius is top viewed as an enabling system: its impact depends on how workflows, roles, and reporting definitions are implemented and governed. The platform’s value typically appears in multiple dimensions, not only one. For example, a well-implemented system can:
However, expert insight also includes what can go wrong. Fleet platforms often underperform when organizations treat them as passive record systems. If users are still allowed to “skip” required fields, close work orders informally, or maintain parallel spreadsheets, the system becomes less trusted over time. Readiness therefore involves not only configuration but enforcement: required fields, validation rules, approval gating, and a governance model that ensures compliance with the process.
Another place where value can appear—or disappear—is in operational cycle time. Many fleets suffer from long work order cycle times due to unclear ownership, delayed approvals, or supplier delays without visibility. A platform can help track those delays if state transitions and notifications are designed to reflect reality. If alerts are not aligned to triggers, teams may still miss deadlines. Therefore, readiness should include notification and escalation design, not only data and workflow states.
Finally, value depends on continuous improvement. Fleet environments change. Vehicles are added or retired. Suppliers are replaced. Compliance rules evolve. A platform that is left static will gradually drift away from operational reality. Expert implementations therefore include a “change governance” process: who proposes changes, who approves them, how they are tested, and how they are rolled out safely.
Fleetgenius is typically used to support day-to-day fleet operations by organizing vehicle-related workflows such as maintenance planning, operational status tracking, and performance-oriented reporting. The exact feature set depends on configuration and modules selected during implementation.
In a mature deployment, Fleetgenius also supports the operational handoffs between departments. For example, it can help dispatch know whether a vehicle is truly available versus “available but with pending compliance evidence,” and it can help maintenance know the exact context for a work order request (scheduled interval vs. breakdown vs. inspection response). That cross-functional value is often the difference between a tool that is “used” and a tool that is “trusted.”
Focus on workflow fit, data readiness requirements, role-based governance, integration scope, and total cost of ownership. Request a documented implementation plan, a module breakdown, and clarity on what support includes during onboarding and post-launch.
A procurement evaluation should also include a workshop-based assessment. Bring representatives from dispatch, maintenance, compliance, and finance. Walk through real scenarios using example assets and example work orders. Ask how the system would handle each scenario end-to-end. The goal is to validate whether workflow states, evidence requirements, and approvals align with your operational definitions.
Request a commercial breakdown by modules, user seats or asset scope, implementation effort, and ongoing support terms. If pricing is customized, ask for the assumptions that drive cost (for example, number of vehicles, integration requirements, and chosen support levels).
To strengthen procurement decisions, ask for a pricing model that clarifies cost drivers. For instance: if integration scope grows, how does that change implementation cost? If you add locations, how does licensing change? If you expand to additional user roles, how do seat costs scale? Procurement clarity reduces budget risk and prevents surprises that can delay readiness.
No. A fleet platform generally manages workflows around suppliers rather than replacing them. The goal is to coordinate supplier work orders, track progress consistently, and preserve documentation aligned with your operational and compliance policies.
Supplier replacement is rarely the actual value proposition. Instead, value comes from coordinating suppliers with internal governance: consistent request creation, consistent completion evidence, and consistent closure definitions. When suppliers are coordinated effectively, internal teams spend less time chasing updates and correcting incomplete documentation.
Implementation timelines vary based on data quality, number of asset records, integration needs, and how many workflows must be configured. The very reliable approach is to request an implementation timeline with milestones and acceptance criteria.
Readiness planning should also include internal timeline assumptions. Even if the vendor can configure quickly, internal data cleanup, user training, and workflow validation take time. Implementation durations therefore depend on organizational readiness as much as vendor effort.
Common requirements include validated master data templates, agreed workflow definitions and approval chains, training completion for key roles, and go-live acceptance testing to ensure reporting reflects operational reality.
Some fleets also require supplier onboarding readiness. For instance, if suppliers must provide completion evidence in a particular way, then go-live may require pilot validation with at least one supplier category. If supplier participation is delayed, the system may not achieve intended closure discipline.
Many fleet organizations integrate with other internal systems. Integration capability depends on your current stack and the platform’s supported interfaces. Ask for integration documentation and test a small data set before full migration.
Integration readiness should consider both technical and operational aspects. Technical readiness is about interfaces and data formats. Operational readiness is about how integrated data affects workflows. For example, if telematics events indicate faults, how do those events map to work order creation? Who validates and closes those work orders? Integrations should be designed so they strengthen workflow discipline rather than create new sources of confusion.
Define success metrics before deployment—such as reduced downtime events, improved maintenance scheduling adherence, increased completeness of compliance documentation, faster work order cycle times, and improved accuracy of asset availability reporting.
Measurement should include process metrics and outcome metrics. Process metrics include compliance evidence completeness rates and work order cycle time. Outcome metrics include operational availability, reduction in overdue compliance events, and improved cost predictability. The system is working when both process discipline and operational outcomes improve.
Fleetgenius can be a powerful operational layer for organizations seeking consistency across dispatch, maintenance, and compliance workflows. The very important takeaway is that the platform’s impact depends on disciplined implementation: correct master data, clear roles and workflow states, a supplier coordination model, and reporting logic that matches how your teams actually operate. When those conditions are met, fleet leaders can move from reactive management toward structured, measurable operational control—without relying on guesswork or fragmented records.
To make Fleetgenius operational control rather than “another system,” treat readiness as a cross-functional discipline. Procurement must clarify scope and commercial terms tied to adoption and support. Implementation must prioritize workflows, governance, and evidence capture. Operations must commit to SOP adherence, training, and continuous improvement. When these elements align, Fleetgenius supports faster decisions, more predictable maintenance execution, and audit-ready documentation that strengthens both day-to-day performance and long-term risk reduction.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans

Explore the Tranquil Bliss of Idyllic Rural Retreats

How to Make Lasting Memories at Disneyland Attractions

4rkojvsx Technology: Industry Insights and Buying Guide

Affordable Phones and Plans for Seniors

Affordable Full Mouth Dental Implants Near You

Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!

Discovering Springdale Estates

Unveiling RS Sul Telecom Services

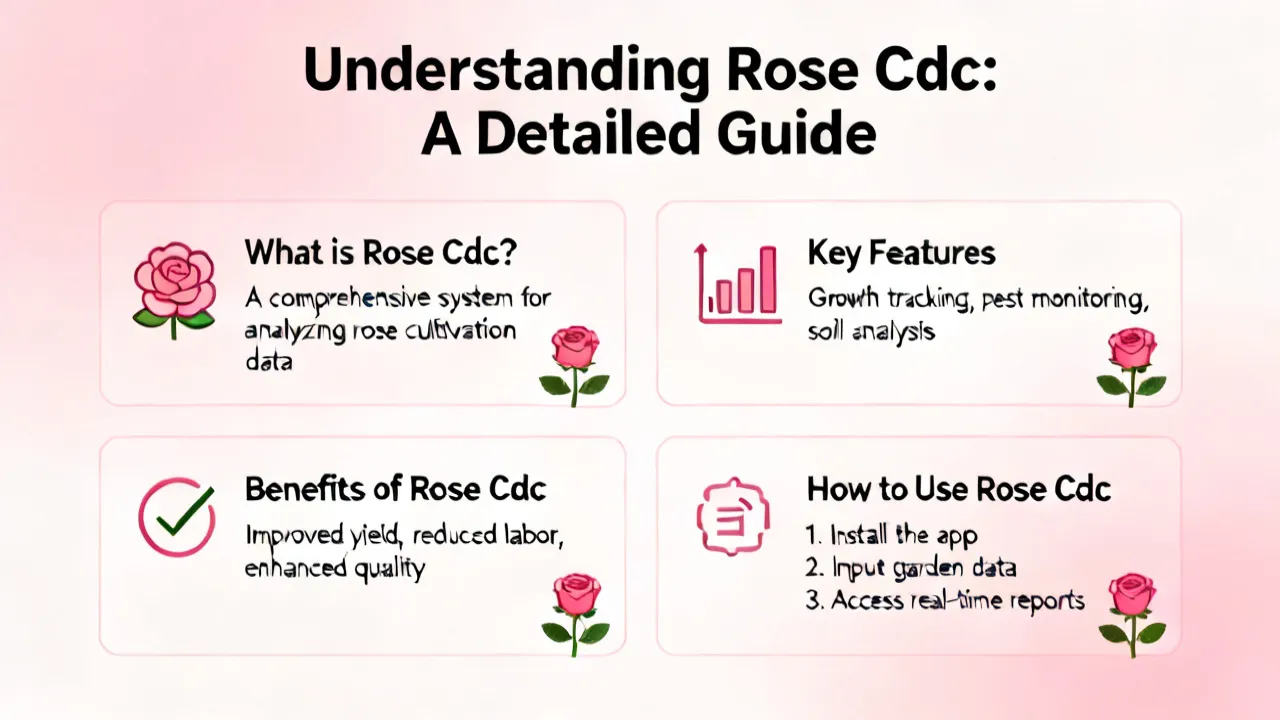
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
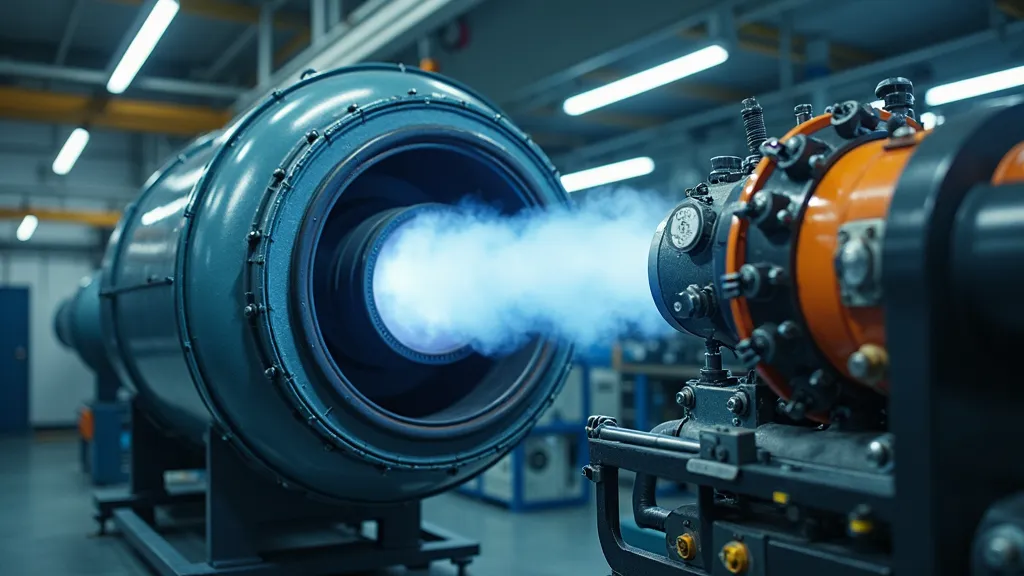
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.
