Fleetgenius helps organizations modernize fleet operations through workflow visibility, maintenance planning, and data-driven decision-making. This guide reviews what fleet management platforms typically cover, why clean data matters, and how suppliers and pricing structures influence total operating cost—using objective, industry-aligned criteria to support procurement and rollout decisions.
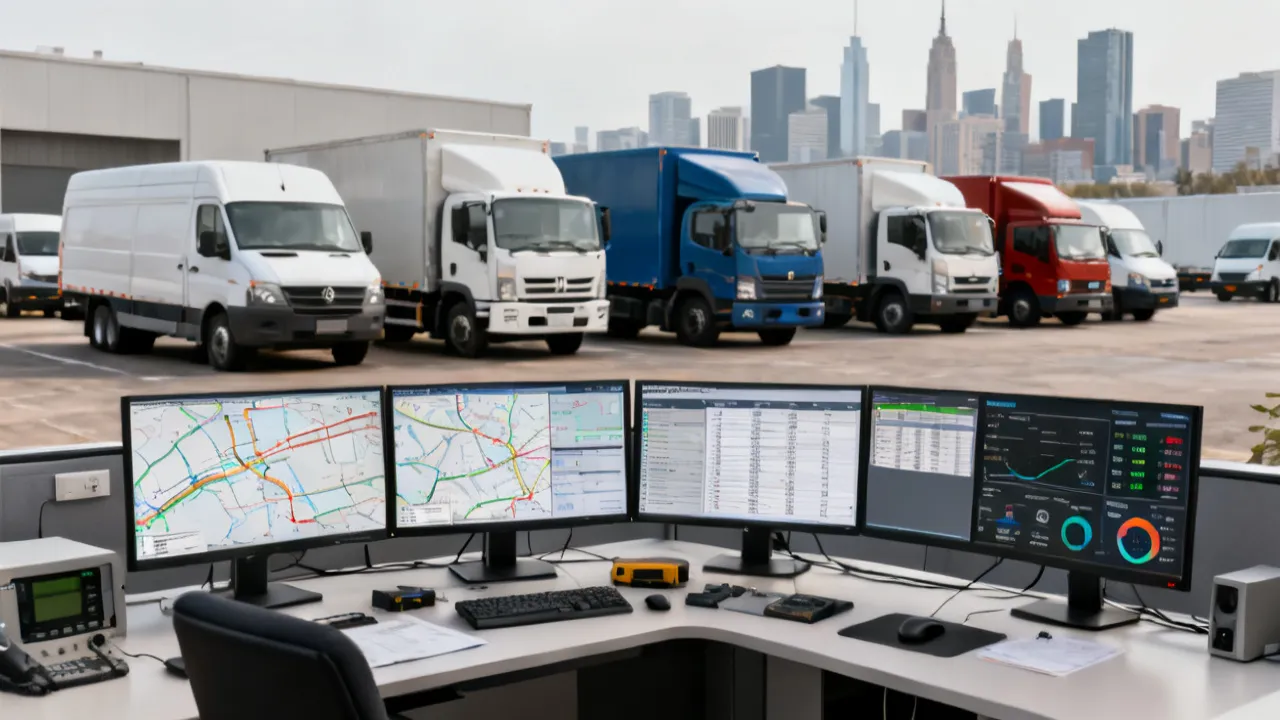
Fleetgenius is positioned as a fleet management solution designed to support day-to-day operational control—especially where maintenance coordination, route or assignment oversight, and performance reporting need to be handled consistently. For procurement teams, operations leaders, and fleet managers, the practical question is rarely “Can we track assets?”—it’s “Can we turn fleet data into repeatable actions with clear ownership, predictable schedules, and measurable outcomes?”
In fleet operations, the biggest losses often don’t come from a lack of information; they come from information that isn’t structured for action. A vehicle might be “in the system,” but work orders might be created manually, preventive maintenance might drift, approvals might happen through channels outside the platform, and reporting might lag behind reality. Fleetgenius-type platforms matter because they’re typically built to close those operational gaps by connecting maintenance workflows to scheduling discipline and performance outcomes.
Decision-makers also need to consider how quickly teams can adopt the tool. Even a technically strong platform can fail if the implementation assumes perfect data, unrealistic training, or a workflow that doesn’t match how technicians, dispatchers, fleet coordinators, and managers actually operate. Fleetgenius is therefore best evaluated as a system of record and workflow engine—something that governs the lifecycle of maintenance and related operational information—rather than as a dashboard-first product.
Finally, fleet decision-makers care about accountability. They want to know who is responsible for creating and closing work orders, who owns preventive maintenance rules, how exceptions are documented, and how leaders can reliably report on what’s happening fleetwide without chasing spreadsheets. Fleetgenius matters because it frames fleet management around consistent processes—planning, execution, verification, and continuous improvement—supported by structured data.
From an industry perspective, a fleet platform earns its place when it reduces avoidable downtime, improves service discipline, and makes exceptions visible. Fleetgenius-type systems typically concentrate on:
However, to evaluate Fleetgenius meaningfully, you should treat these value areas as operational capabilities that must be proven through realistic scenarios. “Maintenance visibility” is not just a screen that shows maintenance history; it’s the ability to schedule preventive tasks reliably, manage work order lifecycles, track documentation, and provide traceability for audits or internal reviews.
Similarly, “operational oversight” should not be assessed as a static list of assignments. The better evaluation approach is to test how the system helps operations teams resolve day-to-day issues: a vehicle goes out of service, an assignment needs reassignment, a backlog of pending approvals grows, or an unexpected failure disrupts the schedule. Fleetgenius should help you see what’s happening, respond quickly, and record why things changed so you can learn and improve.
Performance reporting should also be treated as a decision tool rather than a presentation tool. The key question is whether leadership can make better choices because the platform produces consistent metrics that reflect true operational performance. If the reporting logic depends on data being entered correctly at the right time, you need to validate how the platform supports those behaviors.
Data governance, meanwhile, is often underestimated. Many fleets start with good intentions and then degrade over time as new fields are added, assets are renamed, roles change, or teams create workarounds. A fleet platform should help maintain data consistency through permissions, standardized workflows, and audit trails. It should also support cleaning and correction processes when data errors occur—because errors will happen.
Fleet management tools are rarely priced as a single, universal fee. In very supplier models, pricing depends on a combination of scope and usage. Because you requested that price information and supplier details be incorporated, the very responsible approach is to present pricing factors as a structured procurement checklist rather than asserting unverified amounts. In practice, you should clarify:
Industry note: Gartner and similar analyst sources frequently emphasize that total cost of ownership (TCO) in fleet technology includes integration, change management, and operational adoption—not just the initial subscription. For a reliable reference point, see Gartner’s recurring guidance on enterprise technology value realization and implementation cost considerations (available via Gartner research summaries and official publications).
To compare quotes effectively, it’s worth designing a “cost-to-outcome” view, even if you can’t fully quantify outcomes before implementation. You can approximate the value side by estimating which operational problems the tool will solve, how much time it will save across roles, and how much downtime reduction is plausible. Then you align pricing with the scope of those operational problems.
When vendors provide pricing, ask whether each cost component is fixed or variable. For instance, user-based pricing can become volatile if the organization expands roles or adds new sites. Asset-based pricing can shift if you add vehicles mid-year. Integration-based costs can balloon if data mapping is complex or if multiple systems need ongoing sync.
You should also ask about cost drivers that frequently cause surprises in fleet software:
Another procurement-best-practice is to require a “like-for-like” quote. If one vendor includes a feature and another vendor includes it as an add-on, you may end up comparing products that look similar in marketing but differ materially in what you actually receive under contract.
Finally, consider contractual flexibility and exit conditions. Pricing comparisons should include what happens if you reduce scope, if you terminate, if you add assets, or if you switch integrations. These contractual details often affect the real TCO more than minor differences in base subscription fees.
Even when the software capability looks identical on paper, supplier support quality and deployment context often decide outcomes. Where regional constraints apply—such as local service availability, different compliance expectations, or varying fleet operating patterns—your evaluation should include:
If you have location-specific expectations, replace them with your operational reality rather than assumptions: e.g., how vehicles are serviced, how work orders are approved, and who can authorize parts or services. Those practical workflows are usually where fleets gain or lose time.
To make this concrete, consider how different deployment contexts can change the implementation approach:
Supplier location also affects support. A vendor that can respond quickly and understands your environment can reduce downtime and implementation friction. Conversely, a vendor that relies on general support playbooks and distant escalation can cause delays when you need changes during the pilot.
When evaluating supplier readiness, ask for references that are operationally similar. “Same industry” is sometimes less important than “same workflow pattern.” For example, a vendor may have customers in your industry, but their customers might have centralized maintenance with uniform approvals; your operations might be decentralized and require site-level variation. A strong evaluation accounts for these differences early.
Fleet management software generally sits at the intersection of asset tracking, maintenance operations, and performance analytics. Depending on the organization, the platform may focus more heavily on maintenance orchestration, driver workflows, telematics integration, or reporting. Industry research consistently indicates that fleets look for measurable reductions in downtime, improved compliance, and better asset utilization—outcomes that require both system capability and operational adoption.
For an objective baseline on fleet telematics and fleet management market directions, you can reference reports from reputable analyst firms and industry bodies (for example, research publications by Mordor Intelligence or MarketsandMarkets, and operational top-practice guidance from organizations such as the U.S. Department of Energy’s Vehicle Technologies Office for efficiency and maintenance-related practices). Always treat market-size figures cautiously unless the methodology and assumptions are clearly described in the source.
Beyond market direction, you should focus on category fit. Many products in this space claim “fleet management,” but different vendors optimize for different primary users and workflows:
Fleetgenius, as described in your existing evaluation framing, seems to align with the maintenance visibility + operational oversight + performance reporting pattern. But even within those categories, implementation outcomes vary widely depending on how workflow logic is configured, how roles are defined, and whether maintenance and operational data are treated as one consistent dataset.
Another market reality is that fleet software often lives within a larger ecosystem: vehicle procurement systems, accounting tools, HR and driver management tools, and document management systems. This makes integration and data governance especially important. If Fleetgenius can’t integrate cleanly—or if it requires manual reconciliation—then the tool’s operational value may decline over time.
Therefore, your competitive evaluation should compare not only features but integration effort, operational adoption support, and the quality of workflows end-to-end.
A fleet platform can only be as effective as the processes feeding it. In practice, teams encounter recurring issues:
Fleetgenius evaluations should therefore include a workshop-style demo where you test realistic scenarios: creating a work order, scheduling preventive tasks, recording completion, and generating a leadership report from the same dataset.
To expand on why this matters, consider the lifecycle of a single maintenance event. If a work order is created with the wrong vehicle, or if the odometer reading is incorrect, or if labor and parts details are missing, then downstream reporting will be inaccurate. The leadership team might then conclude that preventive maintenance compliance is low, when in reality the system was missing records—or perhaps the system scheduled preventive tasks based on incomplete or wrong usage metrics.
Even if the platform has advanced analytics, analytics are only as reliable as the underlying data. Moreover, many “fleet improvement initiatives” fail not because the analytics were wrong, but because the operational team didn’t change behaviors. If mechanics don’t know how to record labor correctly, if dispatchers can’t quickly update assignments, or if approvals don’t follow a standard route, the system will accumulate inconsistencies.
Disciplined workflows also help you manage exceptions. In fleet operations, exceptions are constant: a vehicle breaks earlier than expected, parts arrive late, approvals are delayed due to policy thresholds, and vehicles can’t be serviced during scheduled windows. A strong platform doesn’t just ignore exceptions; it captures them with traceable reasons. This enables continuous improvement: you can identify root causes and adjust schedules, suppliers, or operational planning.
Here are data and workflow disciplines you should look for in a Fleetgenius-style evaluation:
These disciplines transform Fleetgenius from a recordkeeping system into an operational control system.
Below is a practical rollout guide that fleet leaders commonly use to reduce risk and improve adoption.
It’s helpful to think of implementation as two parallel tracks: (1) the system configuration and data migration track, and (2) the people and process adoption track. Many projects over-focus on the first and under-invest in the second, which can lead to user friction, partial adoption, and workarounds.
To strengthen adoption, consider the following implementation practices that often determine whether a Fleetgenius-style tool succeeds:
For Fleetgenius specifically, your pilot should prove not only that the system works, but that it produces consistent operational outputs. That means you should pilot with enough volume to test real patterns: multiple work orders per week, enough preventive tasks to validate scheduling logic, and enough exceptions to test rescheduling and auditability.
Also consider “operational coverage,” not just technical coverage. If your fleet includes different vehicle types (e.g., passenger vehicles vs. heavy equipment), your pilot should include at least the most common variations. Preventive maintenance rules and documentation requirements can differ significantly by asset type, and the tool’s configuration must reflect that.
Finally, plan for scaling deliberately. When you expand from a pilot to fleetwide usage, you’re effectively increasing the number of data changes, role interactions, and approvals. A good governance process prevents configuration drift and ensures the system remains stable and consistent.
To make comparisons fair, you’ll want consistent requirement definitions across suppliers. Here is a structured comparison table format for your internal evaluation. (Per your instruction, it contains no links.)
| Evaluation Area | What to confirm | Why it matters for Fleetgenius |
|---|---|---|
| Scope of fleet coverage | How many assets/vehicles, users, and operational sites are included in your plan | Prevents unexpected scaling costs and ensures coverage matches your operations |
| Implementation timeline | Expected onboarding duration, dependencies, and data import approach | Sets realistic rollout expectations and reduces “silent delays” during setup |
| Maintenance workflows | Work order lifecycle, preventive scheduling logic, and document attachments | Directly impacts maintenance compliance and audit readiness |
| Reporting outputs | Which standard reports exist and how custom reporting works | Determines whether leadership analytics are usable without heavy manual effort |
| Integrations | Support for telematics, accounting, procurement, or HR systems | Reduces duplicated data entry and improves operational accuracy |
| Data governance | Roles, audit trails, data retention, and permission rules | Improves traceability and prevents configuration drift |
| Support and escalation | Support coverage hours, incident handling, and change requests process | Maintains operational stability once the pilot ends |
| Pricing model transparency | Clear breakdown of platform cost, onboarding, integrations, and support tier | Enables trustworthy procurement decisions and prevents TCO surprises |
To deepen this table into a practical evaluation tool, you can add questions beneath each row (internally) so the procurement and operations teams ask consistent follow-ups. For example, under “Maintenance workflows,” ask:
Under “Integrations,” ask:
Under “Data governance,” ask:
Procurement comparisons become dramatically more reliable when suppliers must answer questions in the same structure and terms.
When you evaluate Fleetgenius, don’t limit the demo to navigation. Ask the supplier to run scenarios that reflect daily operations:
This approach is aligned with widely adopted enterprise software evaluation top practices: test the workflow, verify the data lifecycle, and confirm that outputs match decisions the business must make.
To further strengthen your demo evaluation, you can require a “dual perspective” walkthrough. That means you ask for:
This ensures you see whether the platform supports both operational execution and management oversight without introducing contradictions. For instance, the system might allow a work order to be closed with minimal fields; leaders might then expect fully detailed labor reporting. The demo should resolve such mismatches and show how requirements are enforced.
During the demo, also pay attention to the “friction points” that can determine adoption success:
Finally, ask the vendor to demonstrate how they support ongoing enhancements. Fleet needs evolve: maintenance schedules change, parts suppliers change, compliance requirements tighten, and operations restructure. A credible vendor will explain how they handle requests for new workflows or fields and what governance model they use to prevent uncontrolled changes.
Even strong platforms face adoption risks. Consider these typical pitfalls:
To manage these risks in a Fleetgenius-style implementation, you can treat each pitfall as a governance and process design challenge:
Another risk is misalignment between the tool’s configuration and the organization’s authority structure. For example, if certain approvals require management sign-off, the system must enforce those approvals. If the configuration allows work orders to bypass approvals, the platform may become a documentation tool rather than a control tool, and compliance might degrade.
Finally, consider the risk of integration dependency. If Fleetgenius relies on telematics or other systems to generate key triggers (like mileage-based preventive tasks), then integration failures could reduce the platform’s effectiveness. In your evaluation, ask how the system behaves when integrations are temporarily unavailable and what fallback processes exist.
Fleetgenius and similar systems tend to appeal to organizations that need structure and repeatability. In many fleets, the pain points include:
A strong evaluation should link platform capabilities to those specific pains, not generic promises.
Operational fit also means the system should match the “rhythm” of your operations. For example, if your maintenance team works in shifts and needs real-time status updates, the platform must support fast status changes and reliable visibility for dispatch and fleet managers. If your organization uses periodic planning cycles (weekly or monthly), the platform must provide reporting and schedule views that match those cycles.
In practical evaluation terms, operational fit can be tested by asking the supplier to answer:
Additionally, operational fit includes how the platform handles common “messy reality” scenarios:
A platform that handles these scenarios well usually creates higher user satisfaction and improves data quality because it reduces workarounds.
When supplier comparison is part of your decision, you should require comparable information. Use a standardized request for proposal (RFP) template across vendors and insist on consistent answers regarding:
This is especially important if you are using a multi-supplier environment or have procurement policies requiring detailed cost breakdowns.
To improve objectivity, you can also require suppliers to provide implementation deliverables in writing. For example, ask them to include:
Procurement teams should also evaluate contract terms that affect operational stability. For instance:
When you include these contract elements in your RFP and scoring rubric, you reduce the risk of selecting a vendor that looks good during a demo but underperforms during operations.
Fleetgenius is typically evaluated for fleet operations support such as maintenance workflow organization, operational visibility, and performance reporting. The “top use” depends on whether your primary need is maintenance discipline, operational oversight, or data-driven reporting.
Compare pricing based on total scope: number of assets/vehicles, user roles, included features, onboarding effort, integration requirements, and support tier. Request a breakdown rather than relying on a single line-item subscription figure.
Not always. Some organizations can derive value from maintenance workflows, record consistency, and reporting even without full telematics integration. If telematics is important to your use case, confirm integration methods, data quality checks, and ongoing operational ownership.
Implementation timelines vary based on data readiness, workflow complexity, integration needs, and training plans. Ask the supplier for a phased timeline and identify what inputs you must provide to avoid schedule drift.
Prepare a consistent inventory of vehicles/assets, standardized identifiers, maintenance history if you plan to import it, and clear definitions for work order roles and approval steps. Data governance and permission rules should be defined early to reduce rework.
Use operational KPIs tied to your initial outcomes. Examples include preventive maintenance completion rate, work order cycle time, frequency of overdue tasks, and documentation completeness. Ensure metrics are defined consistently and validated during the pilot phase.
Clarify scope boundaries, onboarding responsibilities, integration support expectations, training deliverables, support SLAs (where applicable), change-control procedures, and data migration responsibilities. This reduces risk when scaling beyond a pilot.
Yes. Many fleets reduce risk by starting with a pilot scope (a subset of vehicles or one operational unit), validating workflows and reporting, then scaling. Confirm the supplier’s approach to phased configuration and user role expansion.
Fleetgenius can be a meaningful choice for organizations seeking disciplined fleet maintenance operations, consistent documentation, and practical reporting that supports decision-making. The very objective path is to evaluate the system through workflow scenarios, validate data lifecycle behavior, and compare suppliers using transparent scope and TCO-based criteria rather than surface-level feature lists. When you align implementation steps, governance, and measurable KPIs, fleet technology becomes less of an “IT project” and more of an operational engine that your teams can rely on.
To achieve that outcome, focus on repeatability: define preventive maintenance and approvals clearly, ensure the system captures exceptions with reasons, train field teams on their real daily tasks, and connect leadership reporting to actions the organization will actually take. In fleet management, the tool that wins is usually the one that creates a trustworthy operational loop—plan → execute → verify → improve—supported by data that stays clean because workflows enforce it.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans

Explore the Tranquil Bliss of Idyllic Rural Retreats

How to Make Lasting Memories at Disneyland Attractions

4rkojvsx Technology: Industry Insights and Buying Guide

Affordable Phones and Plans for Seniors

Affordable Full Mouth Dental Implants Near You

Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!

Discovering Springdale Estates

Unveiling RS Sul Telecom Services

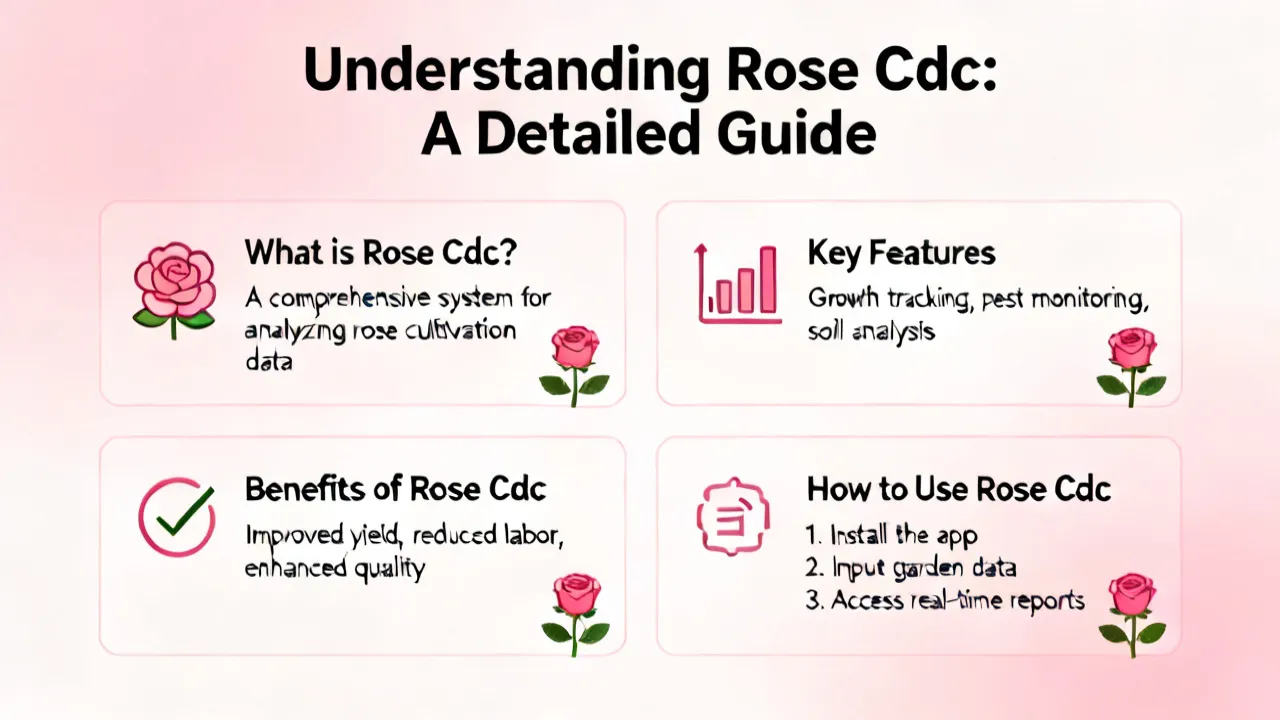
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.
